
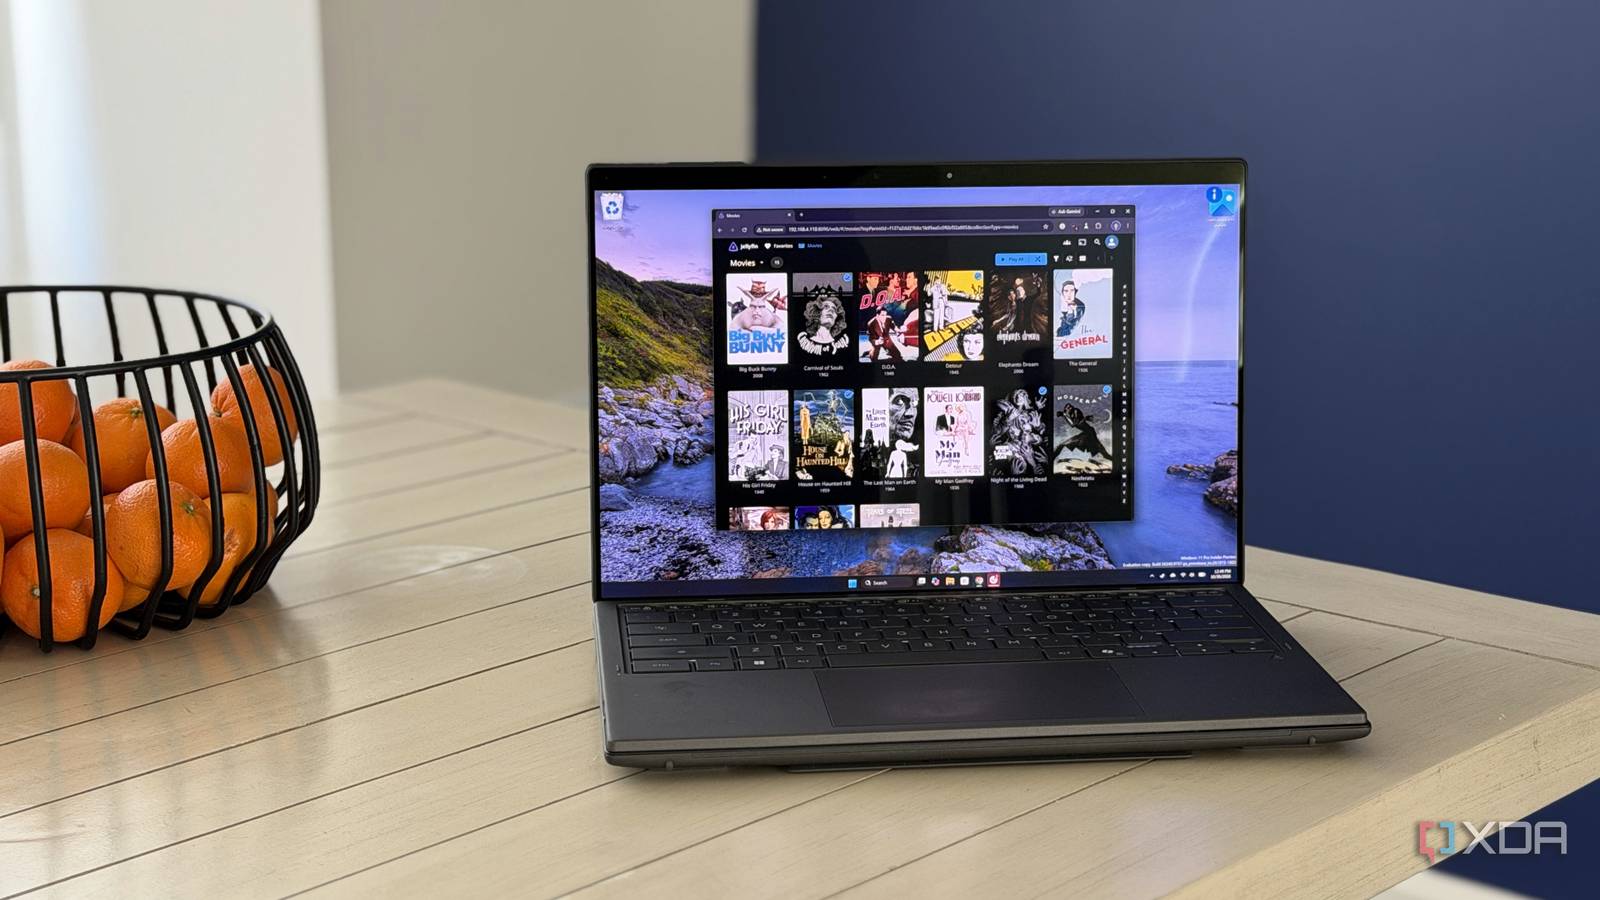
Published Nov 1, 2026, 6:00 PM EST Maker, meme-r, and unabashed geek, Joe has been writing about technology since starting his career in 2018 at KnowTechie. He's covered everything from Apple to apps and crowdfunding and loves getting to the bottom of complicated topics. In that time, he's also written for SlashGear and numerous corporate clients before finding his home at XDA in the spring of 2023. He was the kid who took apart every toy to see how it worked, even if it didn't exactly go back together afterward. That's given him a solid background for explaining how complex systems work together, and he promises he's gotten better at the putting things back together stage since then. I have a mix of streaming services and self-hosted media libraries, and the former is better at recommending new things to watch. I recently switched to Jellyfin from Plex, and things like watch time got lost in translation. Maybe I set things up wrong, which isn't out of the question, but now I have a blank slate for what data Jellyfin can use to suggest things, and that's a problem. It suggested a vampire movie because I watched "His Girl Friday," and that's not even the same genre. Sure, I can go through my library manually, add favorites, and check the watched icon, but that takes forever, and all I really want to do is sit back and watch some movies in my downtime. So, I fed my Jellyfin library to a local LLM or two, and let them give me recommendations based on what I had. They did a surprisingly good job, and while they aren't replacing the inbuilt Jellyfin recommendations anytime soon, they're another tool for figuring out what to watch today. Jellyfin's 'Because you watched' rows don't know what you watched And why my test library was 15 free films Full disclosure: to start with, I tested this on a library of 15 free movies. 11 were public domain and pulled from the Internet Archive (5 horror, 3 noir, 3 comedies), and 4 Blender open movies. This gave me enough of a mix to get recommendations from, but not really enough for Jellyfin to provide good suggestions, just some vague suggestions. Which is fine, really. The test is what the local LLM would come up with. To keep things fair, I seeded the watch history on purpose by marking movies as watched rather than letting them play through. A few things were favorited, and the watch history was purposefully set to be lopsided, with none of the comedy or Blender movies selected. Plus, sometimes recreations and movie scores can have their own copyright. Manually marking things as watched felt the better course of action. Jellyfin was installed inside a LXC on my Proxmox server, the local LLMs were served from the same server via Lemonade, and everything was controlled via PowerShell scripts, to ensure repeatable instructions. Rather than find a plugin I used a script to connect Jellyfin and my local LLMs Then I checked what the model got up to The PowerShell script does a few things that keep the local LLM results honest. It reads the played and favorite flags via the Jellyfin API, sends the list to Lemonade's OpenAI-compatible endpoint, and prompts it to return eight ranked picks as JSON, each with a one-sentence reason naming a watched movie. I used gpt-oss-120b and Qwen3.5-9B, running on the ROCm stack in Lemonade, with the temperature set to 0.3 to encourage more creativity. Each started with a 4,000 token budget, but Qwen splurged all of that in thinking on the first run, so I increased it to 8,000. That's the problem with local LLM thinking models. Sometimes they run around in circles before doing anything. This setup also sidesteps using any part of the *arr stack, while keeping things in a form that I can see happen. Every pick gets graded based on if I've already watched it, already owned it, and if it was a real movie with the correct year (graded via Jellyfin's TMDb lookup). I expected oddness, and the only odd thing was that 31 of the 32 picks were real over the four runs, with none of them mentioning a movie Jellyfin marked as watched. Oh, and the one incorrect pick was a mix-up over the movie's title, which differs between a 1951 original and a later remake. Two models, two (mostly) good results The larger model picks like a film nerd, the smaller read my library first Here's the thing: I would watch all 32 picks. Gladly. In fact, half of them were movies I'd already watched elsewhere and just didn't have in the list of 15 test files. The models couldn't have known that, but it does make their picks stronger because, of course, a film fan would want to see those next. Run Verified real (of 8) In Jellyfin watch history I'd already seen (of 8) Fit the taste (of 8) Time (s) Output tokens gpt-oss-120b, round 1 8 4 8 19.6 883 Qwen3.5-9B, round 1 8 5 8 152.7 4,758 gpt-oss-120b, round 2 8 5 8 24.8 1,080 Qwen3.5-9B, round 2 7 2 8 166.6 5,169 Gpt-oss-120b has more information in its grasp, and it picks like a film nerd. I got some deep cuts to pick up next, things like "The Innocents," "The Cabinet of Dr. Caligari," and "The Thing From Another World." Oh, and "The Maltese Falcon," which I adore and will gladly watch no matter who suggests it. Qwen3.5-9B started by reading my existing movie shelf, and the top three suggestions came from those. All noir classics, picked because I had "Detour" in the watched pile. Then it went into classic horror, with Psycho and The Thing. While it got the movie names and year of release correct, it tried to tell me that The Last Man on Earth was a sequel to Night of the Living Dead, which is preposterous when the latter movie came out four years after it. Then I favorited three comedies to test the changes This mostly worked, but the local LLMs did get a few things wrong The second round of testing threw a curveball at the LLMs. I marked three comedies as both watched and put them in the favorites section, then reran the script. Both models took about the same time to return their suggestions, but they differed in how they picked. The 120b model kept five horror suggestions, and added two comedies to the mix. "Bringing Up Baby" is one I've not seen, and while I've seen "Dr. Strangelove" many times, it's another classic that never gets old. Qwen balanced its choices more with two comedies, and three each of noir and horror, and gave another factual error by saying "The Thing (1951)" was the title, when it should have been "The Thing From Another World." That split also meant the 120b picked based on the movies I watched, while Qwen decided the favorites list was a better indicator. I can't say either approach was better, or worse. Both gave me suggestions that made sense, and more importantly, none of the picks were anything in genres I don't particularly care for. Some of the reasons given behind why movies were chosen got a little creative, whether it was the claim about a sequel that came out four years before, or loose threads like crime elements being the decider. Nothing that would put me off selecting that choice, and maybe if I let them use more than one sentence those reasons would have made more sense. Both models gave me better recommendations than Jellyfin Here's the thing, both models worked to a point. Gpt-oss-120b was better at discovery and at the speed it recommended new movies. But Qwen3.5-9B was better at recommending things from my existing library, without making me go find where I could watch things. That's perhaps the closest match to how Jellyfin and streaming services recommend new things to watch, but I'm not limited to either. I can use the large model to find what I want to add to my library, then use the smaller model to find what I'll actually watch at any given time. The built-in recommendation engine in Jellyfin might be fine once I have a larger library to work with, which is also another option that doesn't require any scripts to run.
I let a local LLM read my Jellyfin watch history, and its movie picks are surprisingly good
Full Article
Original Source
Read the full article at Xda-developers →KhanList aggregates and links to publicly available news content. We do not host full articles from third-party sources. Always verify important information with original sources.